
Alignment has grow to be a pivotal concern for the event of next-generation text-based assistants, particularly in ensuring that enormous language models (LLMs) align with human values. This alignment goals to boost LLM-generated content’s accuracy, coherence, and harmlessness in response to user queries. The alignment process comprises three key elements: feedback acquisition, alignment algorithms, and model evaluation. While previous efforts focused on alignment algorithms, this study delves into the nuances of feedback acquisition, specifically comparing rankings and rankings protocols, shedding light on a big consistency challenge.
In existing literature, alignment algorithms reminiscent of PPO, DPO, and PRO have been extensively explored under specific feedback protocols and evaluation setups. Meanwhile, feedback acquisition strategies have targeting developing fine-grained and dense protocols, which could be difficult and dear. This study analyzes the impact of two feedback protocols, rankings and rankings, on LLM alignment. Figure 1 provides an illustration of their pipeline.
Understanding Feedback Protocols: Rankings vs. Rankings
Rankings involve assigning an absolute value to a response using a predefined scale, while rankings require annotators to pick out their preferred response from a pair. Rankings quantify response goodness but could be difficult for complex instructions, whereas rankings are easier for such instructions but lack quantification of the gap between responses ().
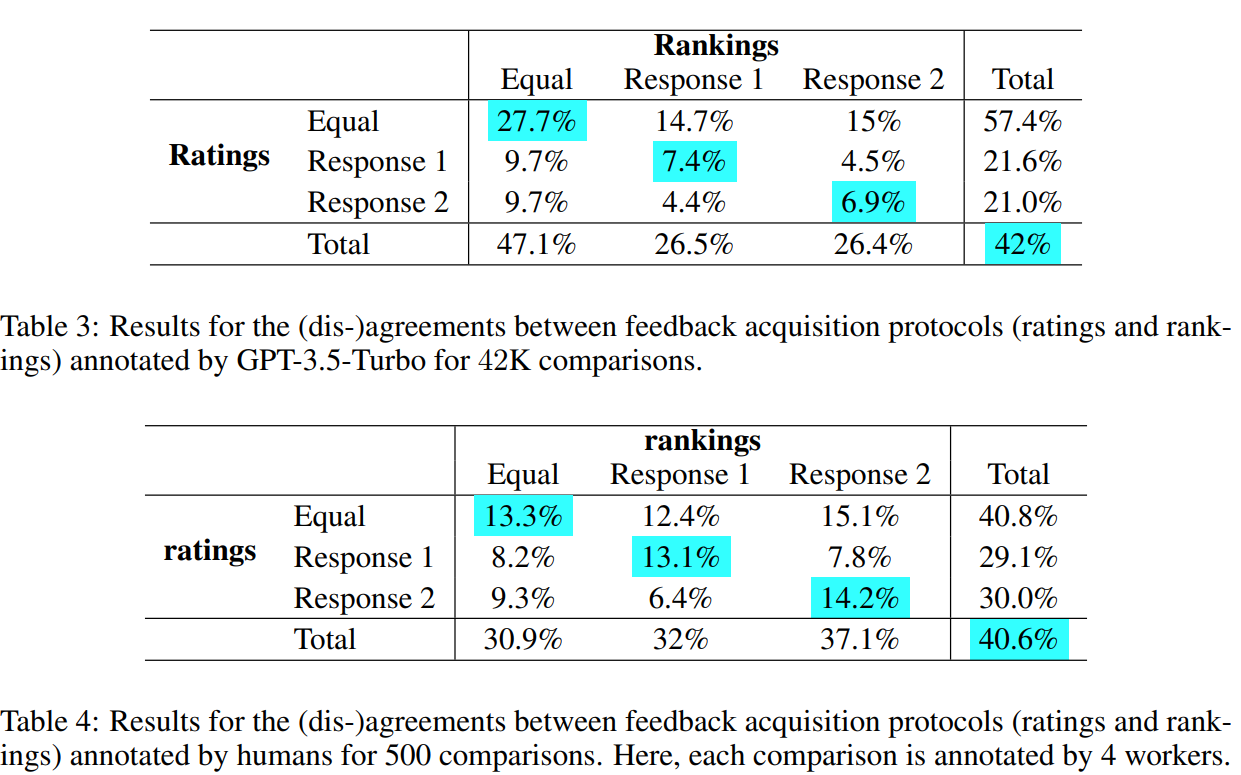
Now we are going to delve deeper into the initially announced feedback inconsistency problem. The authors make use of the statement that the rankings on a pair of responses for a given instruction could be in comparison with convert the rankings feedback data into its rankings form. This conversion of the rankings data to the rankings data allows us a singular opportunity to review the interplay between absolutely the feedback and relative feedback collected from the annotators, independently. Here, they define the term consistency because the agreement between the rankings (converted to its rankings form) and the rankings received by a pair of responses to a given instruction independent of the rankings data.
We are able to clearly observe consistency issues from Table 3 and 4 in each human and AI feedback data. Interestingly, the consistency rating falls inside an identical range of 40% − 42% for each humans and AI, suggesting that a considerable portion of the feedback data can yield contradictory preferences depending on the feedback protocol employed. This consistency problem underscores several critical points: (a) it indicates variations within the perceived quality of responses based on the alternative of the feedback acquisition protocols, (b) it underscores that the alignment pipeline can vary significantly depending on whether rankings or rankings are used as sparse types of feedback, and (c) it emphasizes the need of meticulous data curation when working with multiple feedback protocols for aligning LLMs.
Exploring Feedback Inconsistency:
The study delves into the identified feedback inconsistency problem, leveraging an insightful statement. By comparing rankings on a pair of responses, the authors convert rating feedback data () into rankings data (). This conversion offers a singular opportunity to independently study the interplay between absolute feedback () and relative feedback () from annotators. Consistency, defined because the agreement between converted rankings and original rankings, is assessed. Notably, Tables 3 and 4 reveal consistent issues in each human and AI feedback, with a noteworthy consistency rating range of 40%−42%. This underscores variations in perceived response quality based on feedback acquisition protocols, highlighting the numerous impact on the alignment pipeline and emphasizing the necessity for meticulous data curation when handling diverse feedback protocols in aligning LLMs.
Feedback Data Acquisition
The study uses diverse instructions from sources like to gather feedback. Alpaca-7B serves as the bottom LLM, generating candidate responses for evaluation. The authors leverage GPT-3.5-Turbo for large-scale rankings and rankings feedback data collection. Additionally they collect feedback data under the rankings and rankings protocols.
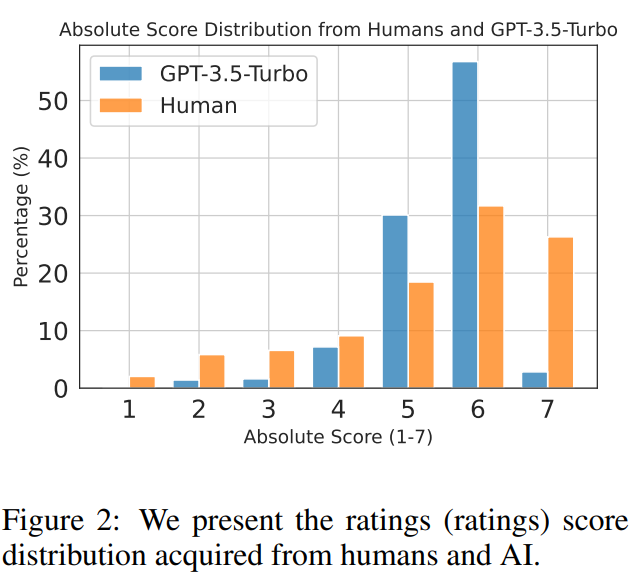
Evaluation of rating distribution () indicates human annotators tend to provide higher scores, while AI feedback is more balanced. The study also ensures feedback data is unbiased towards longer or unique responses. Agreement evaluation () between human-human and human-AI feedback shows reasonable alignment rates. In summary, the agreement results indicate that GPT-3.5-Turbo can provide rankings and rankings feedback near the human’s gold label for the responses to the instructions in our dataset.
Impact on Alignment and Model Evaluation
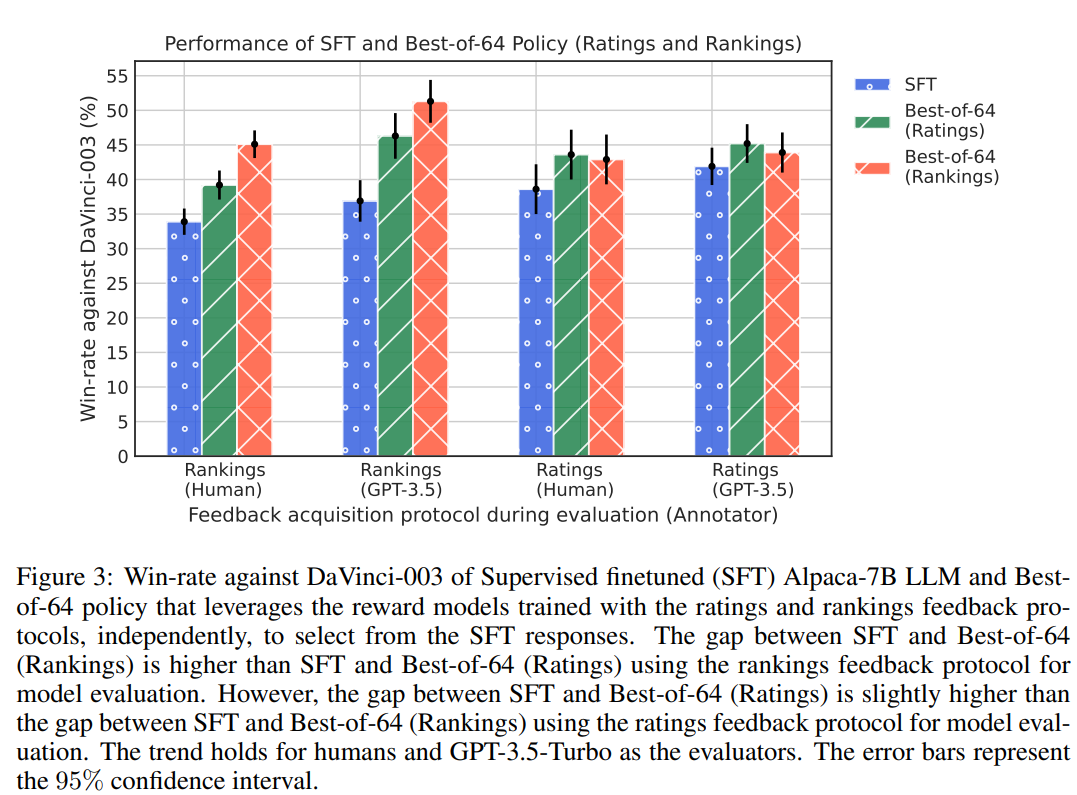
The study trains reward models based on rankings and rankings feedback and assesses Best-of-n policies. Evaluation on unseen instructions reveals Best-of-n policies, especially with rankings feedback, outperform the bottom LLM (SFT) and exhibit improvement in alignment ().
A surprising revelation within the study unveils an evaluation inconsistency phenomenon, where the feedback protocol alternative during evaluation seems to favor the alignment algorithm that aligns with the identical feedback protocol. Notably, the gap in win rates between the Best-of-n (rankings) policy and the SFT is more pronounced (11.2%) than the gap observed between the Best-of-n (rankings) policy and SFT (5.3%) under the rankings protocol. Conversely, under the rankings protocol, the gap between the Best-of-n (rankings) policy and SFT (5%) barely outweighs the gap between the Best-of-n (rankings) policy and SFT (4.3%). This inconsistency extends to evaluations involving GPT-3.5-Turbo, indicating a nuanced perception of policy response quality by annotators (each human and AI) under distinct feedback protocols. These findings underscore the substantial implications for practitioners, highlighting that the feedback acquisition protocol significantly influences each stage of the alignment pipeline.
In conclusion, The study underscores the paramount importance of meticulous data curation inside sparse feedback protocols, shedding light on the potential repercussions of feedback protocol decisions on evaluation outcomes. Within the pursuit of model alignment, future research avenues may delve into the cognitive facets of the identified consistency problem, aiming to boost alignment strategies. Exploring richer types of feedback beyond the scope of absolute and relative preferences is crucial for a more comprehensive understanding and improved alignment in diverse application domains. Despite its beneficial insights, the study acknowledges limitations, including its concentrate on specific forms of feedback, potential subjectivity in human annotations, and the need to explore the impact on different demographic groups and specialized domains. Addressing these limitations will contribute to developing more robust and universally applicable alignment methodologies within the evolving landscape of artificial intelligence.
Try the Paper and Github. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter. Join our 36k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.
In the event you like our work, you’ll love our newsletter..
Don’t Forget to hitch our Telegram Channel
Vineet Kumar is a consulting intern at MarktechPost. He’s currently pursuing his BS from the Indian Institute of Technology(IIT), Kanpur. He’s a Machine Learning enthusiast. He’s enthusiastic about research and the newest advancements in Deep Learning, Computer Vision, and related fields.