
The search to process lengthy documents with precision has been a formidable challenge. Generative transformer models have been on the forefront, dissecting and comprehending extensive texts. Their effectiveness wanes when faced with documents sprawling across tens of hundreds of tokens, revealing a spot in the present methodologies. This limitation underscores the necessity to navigate the complexities of in depth texts without sacrificing accuracy or efficiency.
The recent breakthrough in augmenting pre-trained language models with recurrent memory has marked a major breakthrough. This method, diverging from traditional benchmarks that struggled beyond sequences of 104 elements, showcases a capability to tackle tasks involving sequences as much as an astounding 107 elements. This advancement not only sets a brand new precedent for the input sequence size a neural network can process but in addition paves the best way for models to delve into more intricate and realistic scenarios.
Researchers from AIRI Moscow, Neural Networks and Deep Learning Lab MIPT, and London Institute for Mathematical Sciences introduce BABILong, a pioneering benchmark meticulously crafted to judge NLP models’ prowess in dissecting long documents. By intricately weaving easy episodic facts inside a corpus of book texts, BABILong creates a fancy needle-in-a-haystack scenario. This benchmark tests models’ ability to sift through as much as 10 million tokens, locating and leveraging pertinent information hidden inside an ocean of knowledge. This daunting task challenges even essentially the most advanced models to exhibit their capability to effectively process and understand long documents.
The evaluation of various models against the BABILong benchmark reveals a notable disparity in performance. When GPT-2, a smaller generative model, is fine-tuned with recurrent memory augmentations, it outshines its counterparts, including the more sophisticated GPT-4 and Retrieval-Augmented Generation (RAG) models. This fine-tuning enables GPT-2 to adeptly handle sequences extending as much as 10 million tokens, showcasing unprecedented proficiency in processing long sequences.
This methodological innovation redefines the parameters of possibility inside the domain. By integrating recurrent memory, these models can now engage with long documents in a fashion previously deemed unfeasible. This progression holds profound implications for the longer term of NLP, potentially unlocking recent avenues for research and application that were once beyond reach.
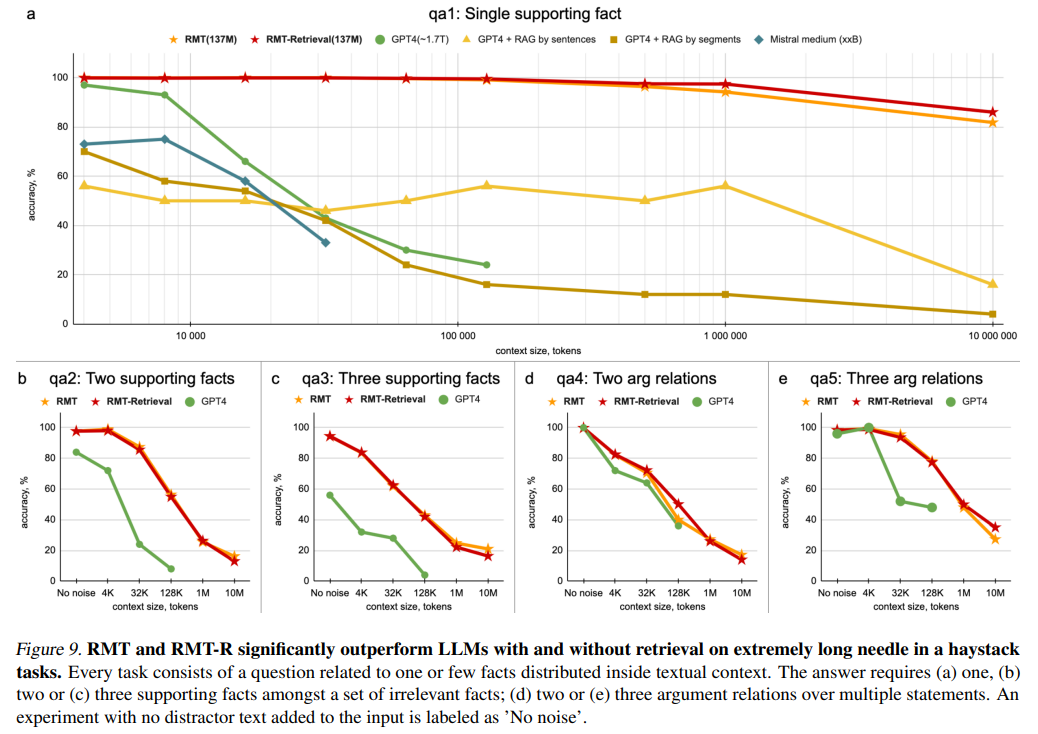
In conclusion, exploring and implementing recurrent memory augmentations for transformer models signify a pivotal development in NLP. The important thing takeaways from this advancement include:
- The introduction of BABILong, a brand new benchmark, addresses the critical need for tools that may rigorously evaluate the performance of NLP models on long documents.
- Superb-tuning GPT-2 with recurrent memory augmentations has proven to be a game-changer, dramatically enhancing the model’s ability to process and understand documents with as much as 10 million tokens.
- This breakthrough showcases the potential of augmenting models with recurrent memory and illuminates the trail forward for developing more sophisticated and capable NLP applications.
Take a look at the Paper. All credit for this research goes to the researchers of this project. Also, don’t forget to follow us on Twitter and Google News. Join our 38k+ ML SubReddit, 41k+ Facebook Community, Discord Channel, and LinkedIn Group.
In the event you like our work, you’ll love our newsletter..
Don’t Forget to hitch our Telegram Channel
Chances are you’ll also like our FREE AI Courses….
Hello, My name is Adnan Hassan. I’m a consulting intern at Marktechpost and shortly to be a management trainee at American Express. I’m currently pursuing a dual degree on the Indian Institute of Technology, Kharagpur. I’m captivated with technology and wish to create recent products that make a difference.